6 verified briefings on Reliability. Each story includes a plain-English summary, why it matters, and the concrete action engineering teams should take.
A new benchmark tested how major PostgreSQL providers handle memory-intensive queries. The test revealed that some popular services, including AWS RDS and Google Cloud SQL, crashed completely, causing significant downtime.
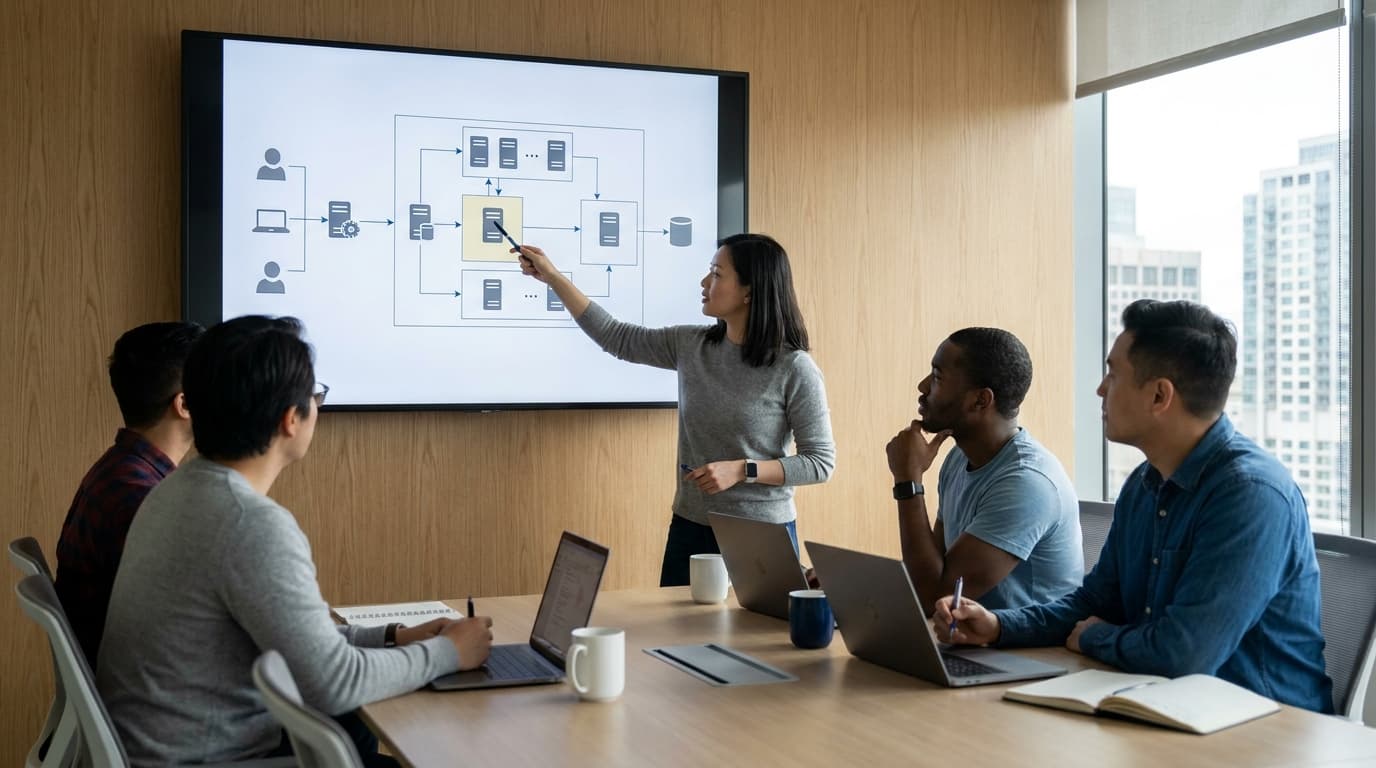
Uber redesigned its open-source M3DB database to better handle server failures. The new system uses small, fixed-size "subclusters" to contain problems, improving overall reliability and making maintenance easier without moving massive amounts of data.
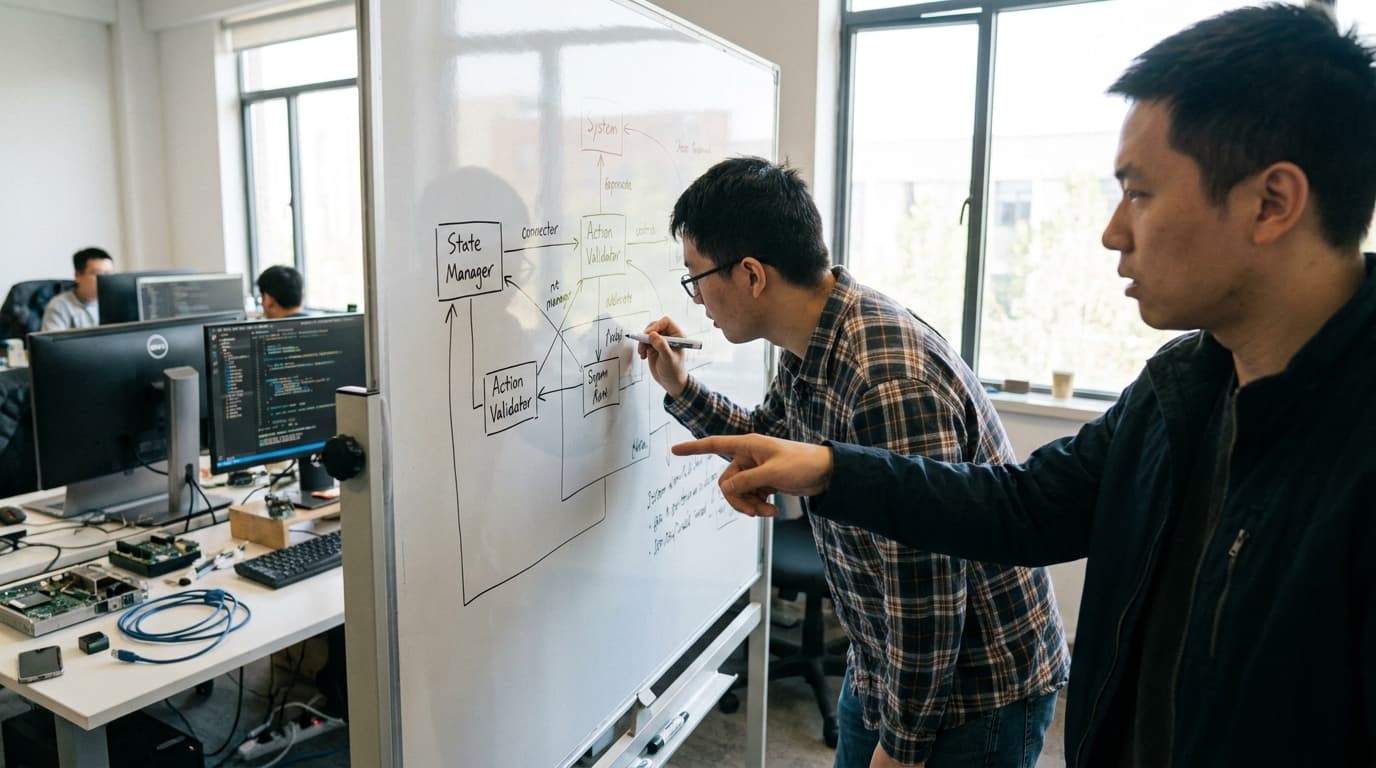
AI agents fail for reasons beyond just model hallucinations. An OpenAI expert shared a framework for building reliable 'agent harnesses' that control state, scope authority, and validate actions to prevent common production errors.
AI agents often fail outside of controlled demos because they lack a proper support system. An 'agent harness' provides the necessary infrastructure and guardrails to make them reliable and trustworthy for real-world use.
Stripe created an automated system that maps its infrastructure to find and fix database problems on its own. This approach significantly speeds up recovery from outages, improving reliability for its global payment network.
A recent analysis reveals that leading AI models from major providers frequently disagree on basic, real-world facts. This challenges the assumption of factual consistency among frontier LLMs and highlights a fundamental reliability issue for developers and businesses building on this technology.